




Manufacturing Engineer & Data Analyst with 18 years of experience, specializing in data analysis, open source contribution, and business automation.


Jump to — Robotics · Baseball websites · Realtime open data · Baseball analytics · Document OCR · Open source · Competitions · Dashboards and mobile · PyPI · Learning projects · Tech stack · Career · Patents · Contact
stackchan-lab — M5 Stack-chan Development Log (Active)
Official M5Stack Stack-chan (M5STACK-K151) moved off its stock cloud assistant onto a self-hosted stack on a Raspberry Pi 5 - 19 server-side tools · 11 device tools over MCP · sings 16 cheer songs · speaks while the model is still writing · stock firmware, unmodified
How the voice loop runs
| Stage | |
|---|---|
| Speech in | sherpa-onnx / ReazonSpeech, on the Pi |
| Reply | hosted 120B model, free tier |
| Speech out | Open JTalk, on the Pi (0.27s per sentence), shaped for a speaker that cannot reproduce bass |
| Tools | weather, FX, indices, crypto, NHK headlines, JMA quake / warning / typhoon, heat index, train delays, on-this-day, moon and sun, fuel surcharge, travel advisories, baseball scores and standings, roster notices, cheer-song lyrics, singing a cheer song |
| Device tools | camera, head angles, LED, volume, screen, battery - called through the same function-call array |
| Interrupting | the device sends no mic while it is playing, so the server stops the audio and listens at a silent point |
| Latency | the reply is spoken sentence by sentence as it streams, and only the utterance that just ended is sent to the recogniser |
What went wrong, and what it turned out to be
| Symptom | Cause |
|---|---|
Pairing failed as No devices found |
Factory firmware nine releases behind. OTA needs Wi-Fi, Wi-Fi setup needs pairing - USB was the only way in |
| Device kept talking to the stock server | A hand-appended NVS entry padded its key with 0xFF instead of 0x00: valid CRC, invisible to my own parser, permanently missed by ESP-IDF |
| OOM-killed at 7GB RSS, twice | A VAD that starts counting at speech never fires on an always-streaming mic |
| Speech played in slow motion | Not length - the same 30 morae read fine as nonsense but break in a real sentence, and one comma puts it right. The server times each synthesis and re-splits what came out slow |
| The rhythm would not come back, whatever I changed | The wall was the ruler. Against a real recording, comparing sound to sound has a floor of 142-680ms: singing at the onsets of the recording itself, which cannot be wrong as rhythm, still reads that, and every difference I had been reading between methods sat inside it. Measured by times against times, with a random control beside it, the notes now land 20-60ms from the onsets against 55-105ms for random - and it sings |
| Conversation sounded quieter than the singing | Not level - band. The singing voice puts over 90% of its energy above 500Hz; the speaking voice puts 73-84% below it, where a speaker this small reproduces nothing. Matching the level in the band that is actually audible fixed what matching the overall level could not |
More of the same, with the measurements behind each, is in the server notes.
Write-up, measurements and tests: stackchan-lab
M5Stack CoreS3 (ESP32-S3) / Raspberry Pi 5 / Python (aiohttp, WebSocket) / sherpa-onnx + ReazonSpeech / Open JTalk / MCP / Opus
rpi5-infra 🔒 (private, config record)
Configuration record for the Raspberry Pi 5 that hosts the robot's server, kept so the box can be rebuilt after an SD failure and so a change like opening a port leaves a trace.
What it records, and what it deliberately leaves out
| Recorded | firewall rules, systemd units, cron entries, listening ports, an inventory of what is actually running |
| Left out | secrets - unit files reference their EnvironmentFile without containing values, and credential files are excluded |
Raspberry Pi OS / systemd / ufw / cron / Tailscale
Minami Baseball OB — Alumni Association Site (In Production)
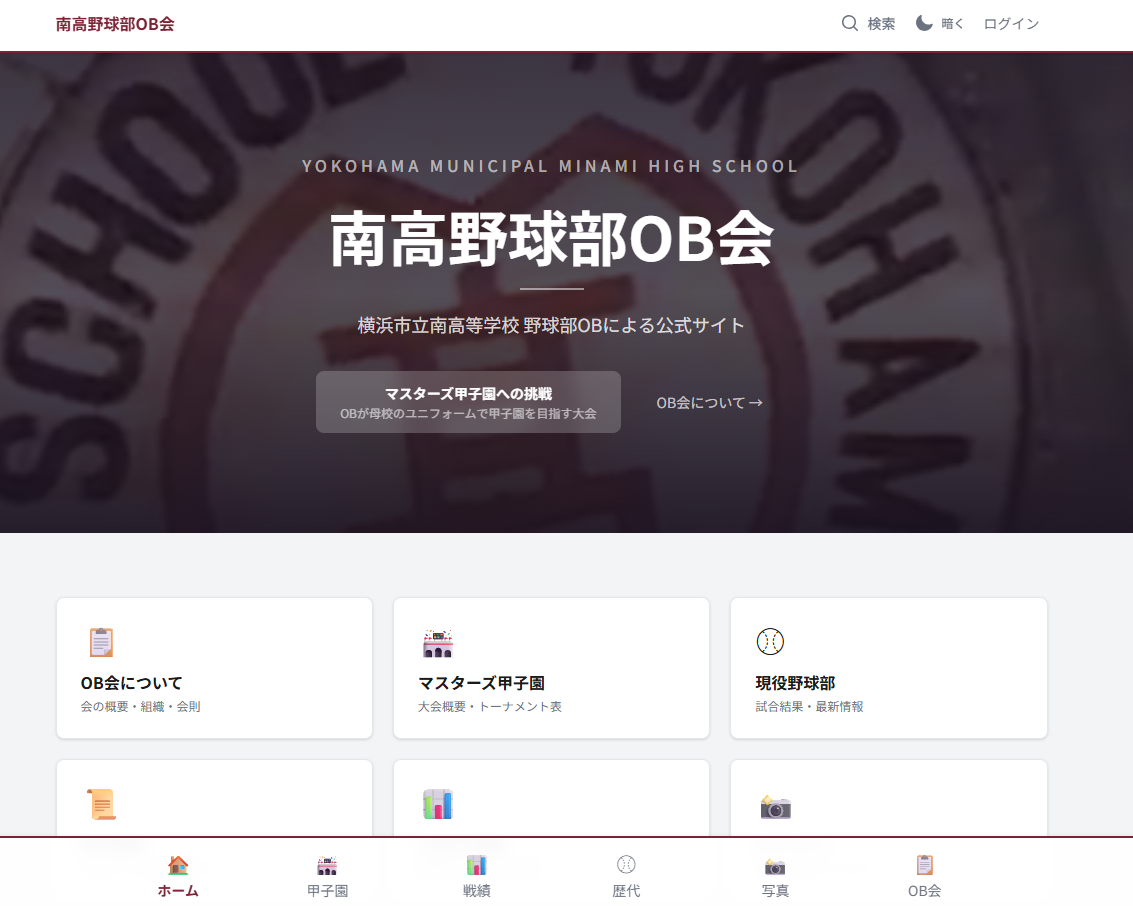
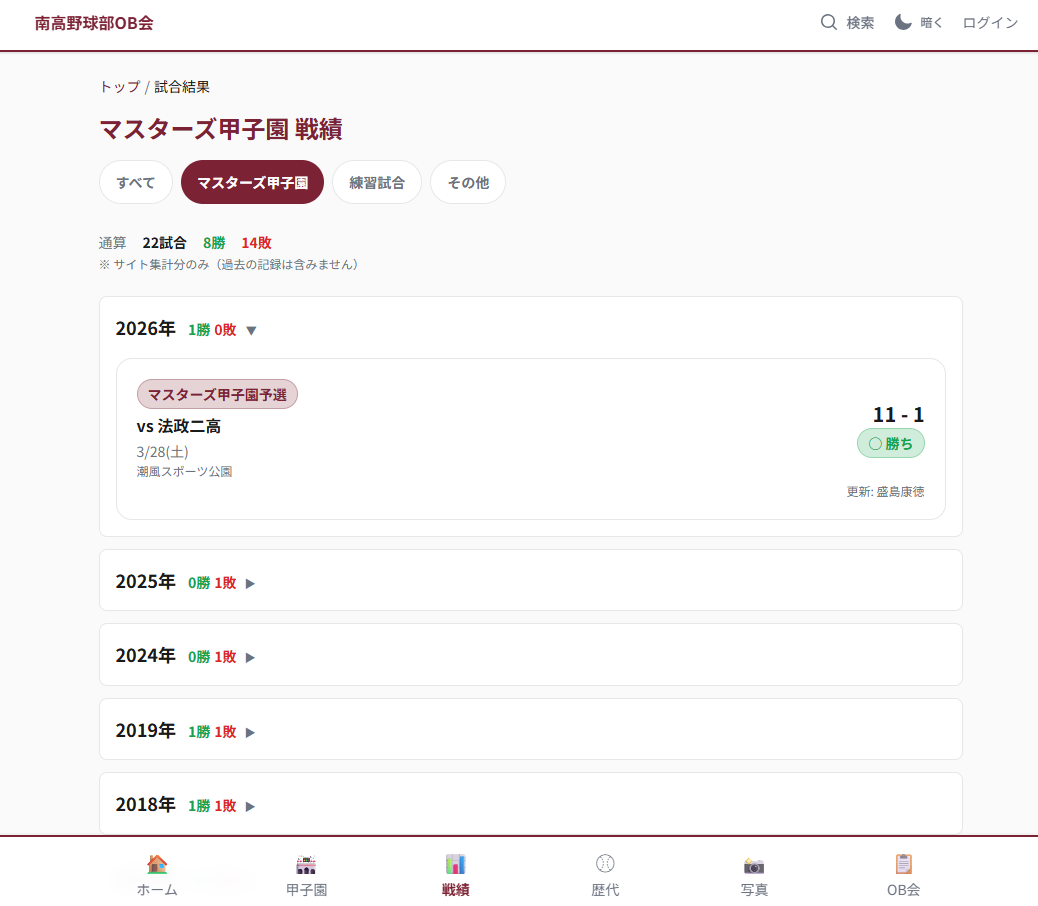
Full-stack web app for a high school baseball alumni association — 11 active users · 44 pages · 23 DB tables · 19 e2e tests · ¥0/mo running cost (157 files, ~18200 LOC). Technical Documentation
| PC (Light) | Game Results |
 |
 |
5-tier RBAC (Middleware + RLS), automated member pipeline (Form → GAS → Actions → Supabase), 686 match records (1955–present)
Architecture & features
- 5-tier RBAC (guest → admin): Next.js Middleware + Supabase RLS — authorization at route, row, and component level
- Automated member pipeline: Google Form → Apps Script → GitHub Actions auto-PR → Supabase role sync. Personal names never touch Git
- Custom CMS: 9 editor pages + 5 inline edit, soft delete (7-day trash + auto-purge), change history, audit logs
- 686 match records (1955–present): cross-source verification, generation-based grouping, per-game photo management
- UX: Unsaved warning, Web Share + LINE fallback, Calendar registration, ripple feedback, Suspense skeleton UI, weather forecast (Open-Meteo, 10 venues), automated game detection (2 sources → auto-PR)
- Security: RLS on all 23 tables (17 main + 6 history),
server-onlyadmin, CODEOWNERS, branch protection, secret scanning, cookie consent, 60-min session timeout - Silent-fail monitoring — built after a 1-month silent outage (a Form trigger silently lost its OAuth grant):
- Hourly health-check probes the full member-request + feedback pipeline (Vercel proxy / dispatch chain / GAS time trigger / gas-issue-form secret match / role-sync recency)
- Workflow-run failure + sync-roles liveness (cron-stall) detection auto-opens a tracking GitHub issue and auto-closes it on recovery
- Dual-channel alerts: GitHub Actions email + GAS Gmail
Next.js 15 / TypeScript 5.8 / Tailwind CSS 4 / Supabase (PostgreSQL + Auth + Storage) / Vercel / GitHub Actions / Google Apps Script / GA4
Yokohama Funnies — Amateur Baseball Team Site (In Production)
Companion site for an amateur baseball team, forked from Minami Baseball OB — 23-player roster · 48 pages · 32 DB tables · 19 e2e tests · ¥0/mo running cost (166 files, ~23300 LOC). Technical Documentation
5-tier RBAC (Middleware + RLS), PR-based member approval (Form → GAS → Actions auto-PR → merge → role sync), custom amateur-baseball stats schema (per-game batting / pitching / attendance) with manual-input + spreadsheet-migration ingestion
Architecture & features
- 5-tier RBAC (guest → admin): Next.js Middleware + Supabase RLS — authorization at route, row, and component level (Google OAuth)
- PR-based member approval (same topology as Minami): Google Form → Apps Script → Vercel proxy → GitHub App auto-creates an approval PR adding a per-member role file (
config/members/<uid>.yml); merging triggers a polling role-sync to Supabase + an approval email to the member — approve by merge. Personal data stays minimal in Git - Amateur-baseball stats schema:
players(jersey / bats / throws / is_guest / photo / comment), per-gamegame_player_batting(14 cols) +game_player_pitching,attendances(○/△/×); aggregated views + client-side season filter compute 打率 / 出塁率 / 長打率 / OPS / ERA / WHIP / K9 - Stat ingestion: spreadsheet migration + editor manual-input UI (
/edit/game-stats, scorebook image side-by-side + per-player grid); editors upload scorebook images straight from the result page - Custom CMS / UX: dedicated + inline editor pages, soft delete (7-day trash + auto-purge), change history, audit logs, public No. 06 ROSTER section (photo + jersey + role + comment) via
players_publicview, Open-Meteo weather forecast with WBGT heat-stress display - Security: Supabase RLS on all tables, anon-readable roster view with sensitive columns filtered, server-only admin, gitleaks secret scanning, notifications isolated on a separate public Actions repo
- Silent-fail monitoring:
- Hourly health-check probes every notification path (Vercel proxy / dispatch ack / GAS heartbeat / feedback webhook secret)
- Workflow-run failure + sync-roles liveness detection auto-opens/closes a GitHub issue, with email alerts on any silent failure
Next.js 15 / TypeScript 5.8 / Tailwind CSS 4 / Supabase / Vercel / GitHub Actions / Google Apps Script
| Japan Geohazard Monitor | Persian Gulf Ship Tracker |
 |
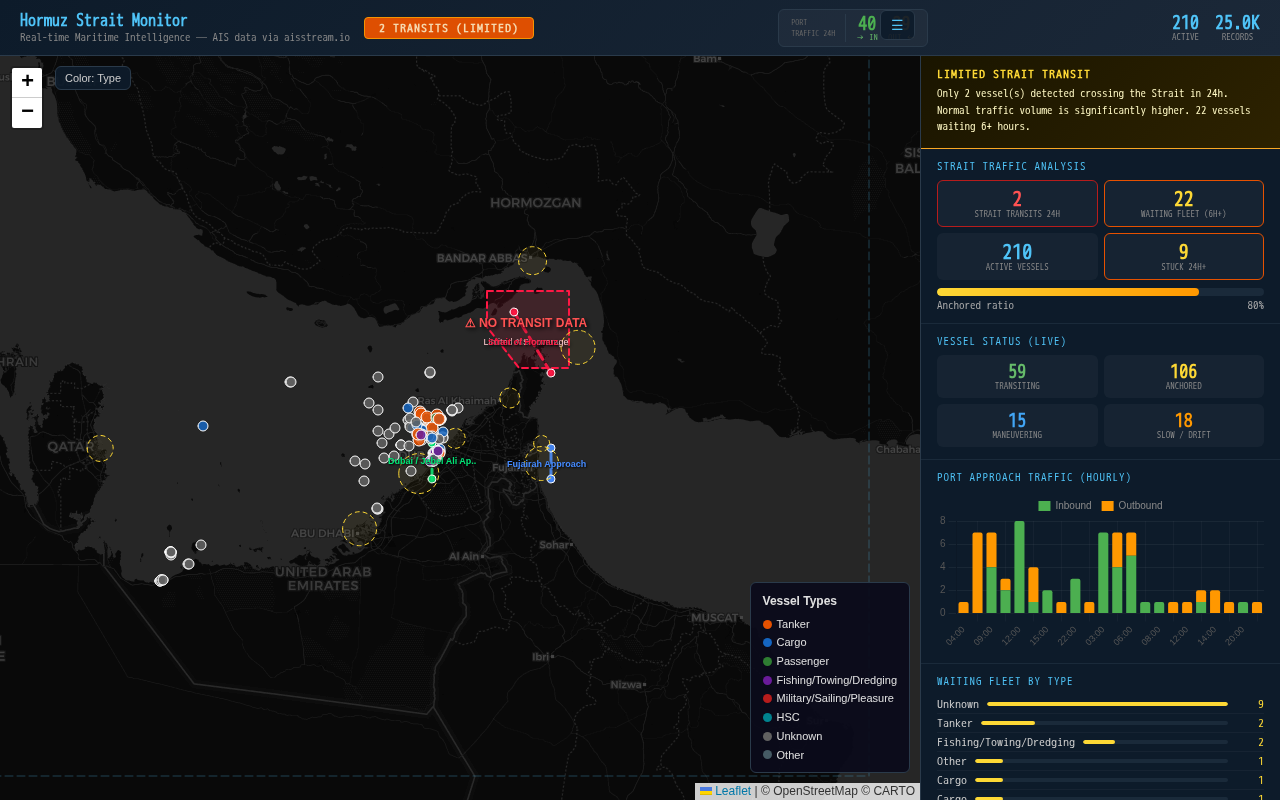 |
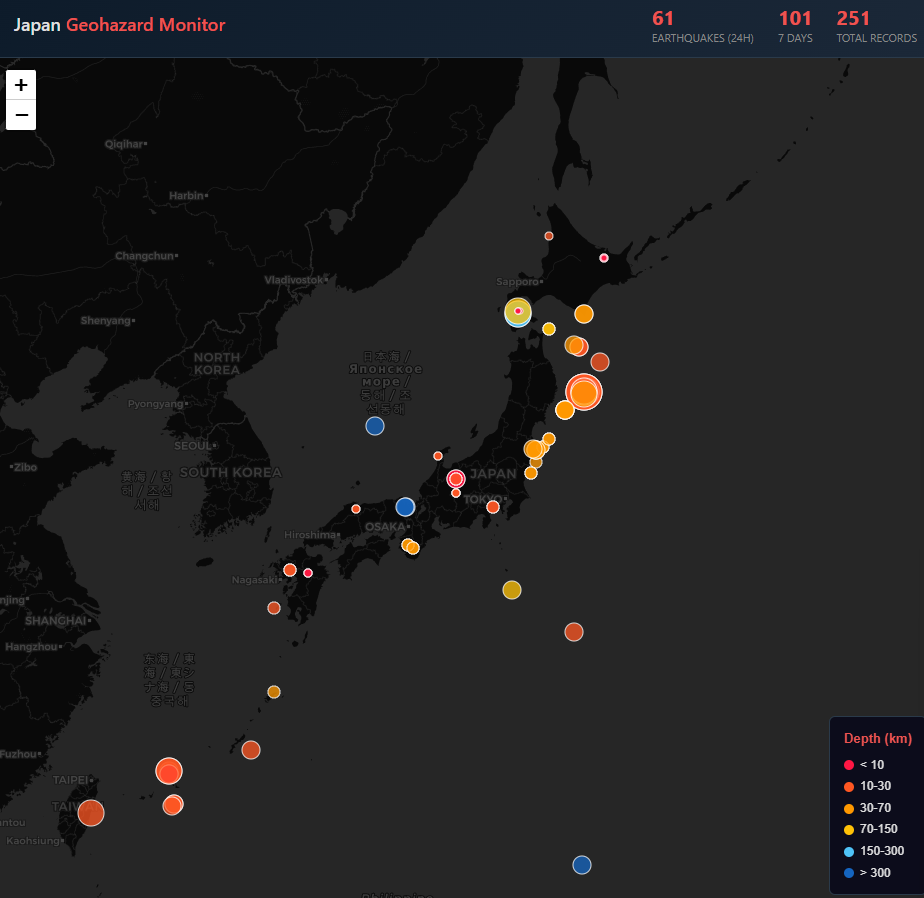
| 31 geophysical data sources → ML earthquake prediction (walk-forward pooled AUC 0.907 over 37 windows; +0.005 per window over a climatology fitted on the same rows) + real-time monitoring dashboard | Vessel tracking across the Persian Gulf & Gulf of Oman. Collection, storage and a browser-side map run on GitHub Actions and a Hugging Face dataset — no machine of my own 🛰️ Sentinel-1 radar now watches the same water, about once every two days, with no account needed. Checked against the project's own AIS archive: 24 of the 24 vessels AIS placed in scored water were found within 300 m — recall only; precision is not measurable from that data. |
Real-time API / WebSocket → SQLite → FastAPI + Leaflet.js (dark theme) — All projects
Japan Geohazard Monitor — Earthquake prediction research
Data sources, evaluation and the Kumamoto InSAR result
- 85 features from 25+ sources — USGS, NASA Earthdata, INTERMAGNET, NMDB, NOAA, IOC
- Walk-forward evaluation — a HistGBT ensemble on a 1° grid, scored on 3,004,835 rows across 37 windows from 1989 to 2026: pooled AUC 0.907, Brier skill +0.080.
- What that number is and is not — most of it is geography. A climatology fitted on the same rows reaches 0.902 on its own, so the part that is forecast rather than base rate is +0.005 per window, positive in 92% of windows. Reading the figure without its climatology overstates it.
- How rounds are judged — a round that returns a verdict is pre-registered before it runs, its scripts and its verifier are frozen by checksum before the first window is walked, and it is read against permutation or twin floors rather than against zero. Exploratory sizings, which decide whether a round is worth running at all, are labelled as sizings and never reported as verdicts. Null results are logged in the same place as the positive ones (research log)
- Current axis: the isolated mainshock — the pooled figure is carried by aftershock sequences, so since 2026-09 the work targets shocks that are not aftershocks of anything larger, in a causally-selected global arena of 2,280 cells over 36 windows, on a bare climatology rather than the shipped forecast. On that axis the causal per-cell predictor stands at 0.62086 over 25 windows, against a per-window cell oracle of 0.9482, and the 0.907 above does not transfer to it
| Where the 0.907 comes from | Arm over its climatology, per window |
|---|---|
| aftershock-driven positives (39% of them) | +0.018 |
| isolated mainshocks (61%) | +0.007 |
| the strict 11% — no M≥4 within 50 km in the prior year | +0.010, and it fails its own interval |
| Rounds on that axis | Per window | |
|---|---|---|
| Aim the readout at large mainshocks (M6.0) | +0.0027 | floored |
| Replace the fitted readout with a per-cell rate counted from past events alone — no model, no feature columns | +0.0086 | floored; beats the fitted version by +0.0059 |
| Smooth that rate toward its neighbours | +0.0029 | floored on the retake. The first attempt passed on the run and failed its own frozen verifier: the contract defined the kernel's separation only as a great-circle distance, and the one formula it did name sat inside a gate; a regular lattice puts hundreds of cell pairs within a billionth of a degree of its hard cutoff |
| Bend the kernel into an ellipse along the local axis of past events | it loses | the control turned across the axis gains instead |
| A width that varies per cell, with no direction in it | +0.00045 | null when the strength is chosen causally; +0.00045 is a strength the contract disclosed up front as picked after seeing it win, and it comes second of ten against a floor that shuffles widths only among cells with the same neighbour count, so the two explanations stay undecided |
| Build the rival arm instead of a third floor (sizing: no contract, no floor) | +0.00047 | a width set from the neighbour count alone, carrying no seismic quantity, cannot be told apart — a statement about the smoother at the edge of the studied region, not about the earth |
| Measure what an edge cell's kernel actually does (sizing; its control worlds are the previous round's own) | +0.00127 | only on the quarter of negatives sharing a window with a positive; it fails on the other three quarters. The gain is a reordering of active cells, not a better rate estimate — the frozen prediction said the opposite, and correction is withdrawn |
| Price the reference levels on that quarter alone (sizing; which cells are in it is defined by the scored window's own labels) | +0.0247 | the arm sits below a causal climatology of the scored event on that quarter, in 88% of windows, while on the whole problem the deployed base rate beats that same climatology by 0.0416 — so no single base rate serves both halves. A claim was withdrawn rather than published: a two-sided rate gains 0.0287 on the quarter, worth 0.0071 pooled, but loses 0.0415 on the rest and 0.0240 on the whole, the roll-up reproducing that loss to seventeen decimal places. A component is not a lever |
| Ask whether one score can carry both base rates (sizing; four rivals and one control declared before the run) | it loses | −0.0004 pooled, and it beats none of the rivals. The "the weight range was too narrow" rival is refuted by its own curve, which peaks inside the frozen range. Across the five additive families the best trade is 2.62 units gained on the quarter per unit lost elsewhere against the 3.00 break-even needs, at the smallest weight measured — a boundary of measurement, not a wall |
| Make the weight vary with the cell's predicted activity, and enter the region below the last grid (sizing; six rivals and controls declared before the run) | both lose | −0.0004 pooled for the gated weight, and no fixed value of it is positive; the own-cell rate below the last grid gives +3e-5 to +9e-5 at t +0.69 down to +0.27, with no weight passing the four conditions. Decisively measured instead: the gain on the quarter runs t +7.6 to +8.9 while the cost elsewhere is unresolved at t −1.6 to −2.6, so the pooled sign is a resolution limit — about two hundred windows against this arena's thirty-three |
| Price two observables that are not counts: when the cell last had a large isolated shock, and its largest past magnitude (sizing; eight families, three design audits before freezing) | both lose, and a sign is decided | −0.00002 pooled for the graded age; the largest magnitude and the negative count weight never leave the arm. The direction declared in advance — a recent shock raising the score — is harmful at every weight, pooled t −3.35 to −23.5. The opposite is not established either: it passes the shape bar at one weight of seven at t +0.79, and a causal path live in 30 of 33 windows returns +0.0000134 at t +0.07 |
| Replace the arm's magnitude factor with the fraction of all past M≥5 events in the cell that reached M≥6, counted in events (sizing; the premise that a lower-magnitude map is a denser copy was refuted first; two design audits and a post-run audit) | strongest frozen branch, narrowed | +0.00183 pooled with all four conditions, +0.00166 on the 25 windows never looked at, beating the isolated-only and row-unit rivals on both. The causal selection rests on the shrinkage value the probes favoured (without it +0.00083, fails); the gain is carried by the all-event denominator; the trade-off between the two sides of the negatives moves along the shrinkage axis rather than disappearing |
| Judge that increment against worlds that move it between cells of matched past count, neighbourhood and arm level (the first run stopped at a gate I had guessed rather than measured; the contract was re-cut with only that gate and the seeds changed) | +0.0018 | floored, rank 1 of 20 on both floors and at the hindsight value. Not blind: the real numbers were the previous row's and a design audit's seed replicate predicted it. A static prior over where, not a signal of when (window-mean AUC 0.7670 → 0.7688); the claim is the increment as a whole, whose two parts nearly cancel; the real arm beats every world in only 4 of 33 windows, so the verdict rests on the mean |
| Carry that increment to the Japan catalogue, 163 cells this family had never scored (power measured before freezing: top five of 100 in 5 of 12 global sub-arenas of that size; two design audits and a post-run audit) | +0.0055 over the arm | not replicated: rank 22 of 100 on the primary floor, 10 at hindsight; the residual floor's 2 of 100 is a number only. The map arm itself sits 0.004 below climatology here. The frozen check failed: density counted cells within 2.0°, a distance lattice pairs sit exactly on, and the run's radian arithmetic dropped 47 of 92 of them. The same knife edge is in the global rows' density, where 526 of 2,280 cells depend on it |
| Build the first term that is not fixed per cell inside a window, from event depth, an observable the reader had always dropped (sizing; the first run stopped at its own gate; a design audit and a post-run audit, both reproduced against the data before being accepted) | +0.00094 | not a depth term. The gate caught trailing sums built as differences of float32 cumulative sums; re-cut as a direct sum of eleven bins, the check passes 19 of 19. The window-constant depth map then passes the four conditions in no reading at any grid point, and the within-window column gives +0.00094050 causally with all four - but the same field with the deep flag deleted reaches +0.00116444 under the same rule, and projecting that direction out leaves +0.00029472, which fails. Its own floors then settled it: a circular shift, a cross-cell exchange inside strata and a permutation in time all beat the real column in 8 windows of 8 -- as do the time permutations of all eight within-window columns the arena holds, in 128 comparisons of 128; a later shape column that did beat its floor turned out to be matched by the row's index inside the window, which carries no content at all -- and the permutation carries no future, so the true within-window alignment is anti-predictive; the gain lives in a cell-window level that averages over later rows; putting that band on the same axis as the score then caught a leak of my own, since read at a row whose trailing window ends up to three days after the target the pre-event elevation is 5.21 and 1.95 to 2.26 when it is not, which puts the earlier 60-target 2.667 inside its own resampling spread; normalised inside the cell it is 1.229 in the last three days before a target and 1.01 or below in every bin past six, so a 34-day horizon spreads a three-day signal over eleven label rows; rebuilding every part of the arm at five horizons then puts the band ahead of it by +0.0046 at three days, +0.0032 at six and -0.0006 at thirty-four, monotone, with the gates passing (the 34-day grid reproduces the frozen one to zero, the causal selection matches in all 33 windows, the verifier 12 of 12) -- but the declared pass wanted all four conditions at three and six days and 20 of 33 positive windows is 0.606 against a 0.60 threshold, so the contract says report the numbers and put no story on them, and there is no floor here; the floored judgement written next was abandoned without a verdict by its own contract, because the control carrying only the per-cell map ranked 1 of 100 against the floor while the one carrying the map without its time alignment failed at 73 -- the strata keep a rank correlation of 0.990 with the true map and still leave 54 to 83 per cent of its spread inside a stratum, so a stratified exchange cannot floor a heavy-tailed per-cell quantity, and the real column was neither printed nor read; the replacement floor, which permutes inside each cell when the band took each of its values, was broken by the same two empty columns that broke this family before -- the within-window cumulative count at rank 1 of 100 and the row index at 3 -- so that is a fourth break, three at 34 days and one at three, and the family closes for this arena; kept positives sit at window position 0.5056 against 0.5000 for negatives, a route by which anything smooth in the window clock beats a scrambled copy of itself while carrying nothing; the third floor, in which a cell reads its own real series from another part of the record, passed every gate and was abandoned as well, both controls ranking 1 of 100 -- and the fault is theirs rather than the floors: each predicts alone, the per-cell mean at 0.6007 on the active subset and the cumulative count at 0.5331, and the mean loses three quarters of its increment when made causal, so both carry the contemporaneity this floor destroys. A column is content-free only against a particular floor, which withdraws that word from the cumulative count; the row index, which is content-free, broke the previous floor by itself, so that conclusion stands |
| Ask which dimension the arc is working in, and bound the one that can be bounded (sizing; no floor; all 25 scored windows had been seen) | +0.038 | ordering cells by their in-window rate is optimal among window-constant scores and reaches 0.9482, so the room is there; but a static score, one number per cell fixed in every window, cannot exceed 0.8112 however it is fitted, including on the scored labels -- the mean over windows depends only on the cell ordering, and no pair of cells can contribute more than the larger of its two pair masses. Posed directly as a prediction problem, will this active cell hold an isolated M6 this window, with thirty catalogue features cut before the window and training only on windows whose scoring had finished by that cut, it reaches 0.62086 against the arm's 0.58288, higher in 23 of 25 windows. That splits exactly three ways: +0.0075 is row-level jitter the arm pays and a per-cell score does not, +0.0131 is being a better static map, and +0.0174 is the estimate being recent -- the last isolated by refitting on features from older cuts, which stays causal and only loses information. An audit returned three blockers, all mine and all reproduced before being accepted: the static family is not used up (its honest estimate is 0.6034 against the proved 0.8112, because 510 of the 1,141 cells that ever fire do so in exactly one of the 33 windows), a lag comparison that looked like a drop is -6e-7 once the window sets are matched, and the time-since-last-event features are the count channel behind a sentinel for cells that never fired |
| Ask whether fields that do not count the cell own earthquakes can estimate the map the catalogue cannot (sizing; no floor; a permutation floor on the single fields only; all 25 windows already seen) | at most +0.003 | twenty-seven static fields from trench geometry (USGS Slab2, CC0), the plate boundary steps of Bird 2003 (no licence statement) and the strain rate of Kreemer et al. 2014 (CC-BY-NC-SA, a local input only, nothing derived from it published). They carry real information about which cell -- nine of twenty-seven are outside a Bonferroni band against a within-arena permutation floor, the strongest a Gaussian-weighted subduction velocity at 0.5617, z +8.05 -- and are still decisively worse than the catalogue as a map: 0.55642 against 0.60445 for the causal static map, -0.048, three of twenty-five windows up. On top of the catalogue three of the four like-for-like differences are indistinguishable from zero, so the result is an interval and not a sign: the data exclude a gain larger than about +0.003 against a room of 0.21. Not the learner: a fit allowed to read every scored label reaches 0.54447. The reason is measured -- distance to the nearest plate boundary tells arena from non-arena at 0.904 and tells 0.5085 inside it, so the seeding rule has spent tectonics already. Recorded defects: a verdict line that implemented a rule the contract does not contain, a mark called static and causal that reads later windows, a declared gate that asserted nothing, and six of 5,819 boundary steps whose midpoints an arithmetic mean of longitudes placed on the far side of the planet |
| Ask whether the room the proof left open is learnable, by fitting the static ordering on one half of the windows and scoring it on the other (sizing; no floor; twelve of the fourteen fits train on later windows and are cross-validated rather than causal; all 33 windows already seen) | +0.0212, and 0.2965 where there is no precedent | Fourteen fits over seven splits under four rules reach 0.5726 to 0.5883 held out against 0.769 to 0.810 in sample. My first reading of that gap -- the room is not learnable, the static family is closed -- was wrong, and an audit returned three blockers and five serious findings, each recomputed from the primary counts before being accepted. What is broken is coverage, not fitting: decomposed by how often a cell fires, the 510 cells that fire in exactly one of the 33 windows carry 0.1935 of the positive mass and fall from 0.6052 to 0.1505 when their own window is withheld, while the 368 that fire three times or more carry 0.6184 of the mass and hold 0.8262 against 0.7482. Held out, 0.6638 of the positive mass lies in cells that also fired in the training half and scores 0.7361 there, close to hindsight; the remaining 0.3362 scores 0.2965, below chance, because a map fitted on labels must bury a cell with no precedent at the bottom. The static family is not at the arm's level either -- the smoothed map is 0.5997 against the arm's 0.5785, higher in 28 of 33 windows, while an activity map that reads no label is 0.5557 -- and its learning curve is still rising where the test side can measure it, 0.5542 to 0.5981 for k of two to twenty-four. Geology does not reach the hole: on cells with no precedent the strongest tectonic fields are at or below chance and a hybrid that orders them by the strongest field changes nothing, -0.00046. Also recorded: a declared pass line that could only return one of its two answers, a contract clause computing each half's own ceiling that was never run (those ceilings are 0.8445 to 0.8604, so 85% of the in-sample excess is the ceiling rising), and a best-held-out split that is best only because the later windows are easier on every yardstick |
| Price the coverage problem on the sudden axis itself: split the ACTIVE pair mass by how many isolated M6 events a cell held before the window, and bound what re-ordering cells inside those classes could buy (sizing; no floor; the ceilings read the scored labels by construction; all 25 windows already seen) | 0.87777, which is below the goal | The window AUC decomposes exactly over the 16 (positive class, negative class) blocks, and the blocks sum back at 1.11e-16. Fifteen per cent of the ACTIVE positive mass sits in cells with no precedent, falling from 0.2665 in the first scored window to 0.1016 in the last. Blocks whose positive has the higher class carry 0.4432 of the mass at 0.8924, the four diagonal blocks 0.2983 at 0.5859, and blocks whose positive has the lower class 0.2585 at 0.1956. The oracle bounds for the no-precedent mass -- 0.6586 if it scored a half, 0.7352 if perfect -- are not reachable by flattening, which was measured: every constant offset, collapse or de-separation of that class loses more than it gains (0.60931, 0.59210, 0.57435 against 0.62086). The class ordering is calibrated (observed rates 0.0781/0.1189/0.1118/0.1688 against predicted 0.0771/0.1109/0.1295/0.1701) and shrinking it loses. What remains is ordering cells inside a class, and that family is now bounded: the ratio order reaches 0.86882, a better key 0.87568, a swap polish 0.87581, and maximising all sixteen blocks separately bounds the family at 0.87777 -- below 0.90, so with this class placement no within-class rearrangement reaches the goal and at least 0.0222 must come from placing the classes better. The cell oracle is 0.95017. The requirement is a number: a total of 0.80 needs a within-class AUC of 0.8427, against 0.5859 today. Within-class ordering does exist against a floor that preserves class levels (0.5859 against a null of 0.4993, spread 0.0071; two-degree smoothing 0.5981 where neither cell has a precedent, z +5.69 against a null sharing one relabelling across windows), but at the size of hundredths. Twelve defects of my own are recorded, including a null built at the wrong level whose decision line is retracted, a requirement I understated as 0.83 when it is 0.9061, a "ceiling" that was a lower bound by 0.0070, a claim that the class placement was not the bottleneck which its own bound refutes, and six declared gates that cannot fail by construction |
| Ask what separates two cells with the same earthquake history: build the moment budget the geodesy loads against what the catalogue has released, then bound what any static map could do inside those classes (sizing; no floor beyond a within-class permutation; the bound reads the scored labels; all 25 windows already seen) | empty, and 0.81106 | The budget -- released moment as log10 of summed 10^(1.5m+9.1) before each cut, loading as the GSRM strain-rate invariant, compared as differences of standardised logs because per-cell elastic constants are unknown -- reaches 0.4946, 0.4972 and 0.4987 inside the precedent classes against a null of 0.5000, spread 0.0070, cut 2.48, while the predictor reaches 0.5859 there. Not a relabelling of the class (correlations -0.55 to -0.43), simply flat, and flat across the whole weight sweep 0.5082 to 0.4842. Then the map family itself: restricting the pair-mass argument that proved the 0.8112 static ceiling to same-class pairs bounds any single fixed number per cell at 0.81106 inside the classes, against 0.94203 for a score re-estimated each window and 0.58592 today; the same code without the restriction reproduces 0.811209. Along the measured blend that is a total of about 0.779 for a perfect static map and 0.86882 for perfect window-to-window resolution, so the distance to 0.90 splits three ways and the last 0.031 is the class placement. The audit found my own gate unfailable -- it asked whether the released moment changes when the cut moves a year, which it does for any cut, and a moment leaked 30 or 180 days past the cut passes it 25 of 25 -- so the round has no test of the causality it gates, the second unfailable gate in a row; the printed "Spearman" used ordinal ranks against tie blocks of thousands, the release rate was the released moment plus a constant, the overdue term was a sentinel where no cell has a precedent, 300 draws let the test flip with the null seed, and a pass line was declared at 0.80 for a requirement of 0.8427 |
| Ask whether active faults separate cells that share an earthquake history, and rebuild the floor when the first answer turns out to rest on a units bug (sizing; floor = within-class permutation matched to the candidates' smoothness; all 25 windows already seen) | null inside the classes, real where there is no precedent | Eleven per-cell fields from the GEM Global Active Faults database (CC-BY-SA-4.0, local input only, nothing derived published), 13,696 traces sampled every 5 km, coverage measured first: 1,545 of 2,280 cells hold a trace, median distance 37 km. Two build gates failed and were repaired rather than loosened -- an earth radius of 6371.0088 against the 6371.0 the rest of the code uses, and thirty records with a literal nan depth that float() accepts. The first measurement passed two fields; an audit then found that the arena's distance matrix is in DEGREES (111.195 km per unit), so every "300 km" kernel reached all 2,280 cells instead of 50, five of ten fields were global rather than local, and the floor I had built to be "spatially matched" was hemispheric. Two earlier withdrawals made on that floor are retracted: with true kilometre floors the subduction-velocity field survives inside the classes, and in the no-precedent block the predictor, the half-degree and one-degree smoothed counts all survive. Rebuilt in kilometres, with gates chosen to be failable -- the cell assignment now checked against an independent nearest-centre search instead of the key that produced it, and a new gate on how many cells a kernel reaches -- every fault field falls inside an eleven-candidate cut of 0.0231 in the diagonal blocks, so faults do not order cells that already have a history. But in the block where neither cell has a precedent, cut 0.0587, six of eleven fault fields clear it along with plate-boundary age 0.6146, trench density 0.6028 and the two-degree smoothed isolated-M6 count 0.5981 |
| Build a predictor for the cells with no precedent -- the 15% of positive mass a label-fitted map must place last -- and floor it twice (floors: labels shuffled inside the population, and the static fields shuffled across cells, 20 worlds each; all 25 windows already seen; the fields were selected on these same windows) | +0.0151 of field, +0.0194 of refitting | In the block where neither cell has a precedent the causal model reaches 0.61538 against 0.58084 for the general predictor, and ranks first of twenty-one against both floors; a deliberately leaked fit scores higher still, 0.6326, so the causal restriction binds. Then the audit's controls shrank it. Refitting the general predictor's own thirty catalogue features on this population alone already reaches 0.60026, so most of the gap is population specialisation, not new data. The seven fields do not combine: dropping each in turn, five of seven make the model better by their absence, and the whole model beats plate-boundary age fitted alone by 0.0008 (0.6154 against 0.6146) -- and that field was itself selected on these windows, a selection neither floor prices, so one-in-twenty-one is not an operating error rate. On the whole axis the splice is +0.00171, which decomposes into +0.00380 of ordering and -0.00209 of level (published as -0.00256, which did not sum, and corrected in the next entry), the new model being miscalibrated (0.0874 against an observed 0.0769). A training rule I advertised as stricter excludes nothing the old one did not, and its assertion takes a minimum over the set its own condition defines, so it cannot fail. The scored population is chosen using information from inside the window, and the static tables are present-day compilations built from a record that includes the scored windows -- a leak channel no gate here can see |
| Calibrate before splicing, and measure the selected field on windows that never chose it (sizing; floor = a cell shuffle on the early windows only; the calibration rows are out-of-sample; all 25 scored windows already seen) | +0.0001 of at least +0.0040 | A monotone calibration fitted on earlier windows moves the axis from 0.622572 to 0.622675, and Platt to 0.623334. I called 0.624663 the ceiling any monotone calibration could reach. It is a lower bound, and the same log printed a leaked isotonic map -- monotone, inverting no pair -- at 0.626522 eleven lines below it; one constant added to the raw scores reaches 0.624800. So the level cost is a calibration problem after all, and what is true is only that the two causal calibrators recover +0.0001 and +0.0008 of a gap worth at least +0.0040. One cause is measurable: the calibration rows come from windows whose no-precedent population fires at 0.0977 against 0.0769 in the scored ones. Plate-boundary age does hold on the eight early windows at 0.5665, p 0.0050 against a cell shuffle and 0.0398 once the choice among seven fields is priced, but all seven fields are lower there, by 0.0399 on average, and that population is not the same one -- 576 eligible cells against 655, and 0.2235 of the positive mass against 0.1532. Three of five gates cannot fail: the monotonicity gate passes a constant map whose block AUC is exactly 0.5, the leak gate passes a leak turned into a no-op, and the causality gate never touches the calibration path |
| Bound exactly what the best possible intervention on one precedent class is worth, for all fifteen unions of the four (sizing; no floor; the maxima read the scored labels by construction; all 25 windows already seen; brute-forced against 9,765 enumerated instances) | 0.897957 for the best pair, below the goal | Maximising a weighted AUC over a total order with one sub-sequence frozen is a sequencing problem with chains, so the maximum is exact rather than bounded. Single classes reach 0.7328, 0.7410, 0.7210 and 0.8288; the best pair 0.897957; the triple omitting the class with three or more prior isolated events only 0.878723. To exceed 0.90, then, the re-scored set must touch that class and at least two of the other three -- necessary, never sufficient. The optimum for the no-precedent class takes 85.7 per cent of its gain from the cross-class blocks and 14.3 per cent from the block where neither cell has a precedent, and it does not even take that block perfectly, which withdraws a sentence the previous entry left standing. An audit enumerated every order consistent with the frozen chain over 9,765 instances, 1,499 of them with the frozen scores in the exact reverse of ratio order, and found no discrepancy in either direction; an explicit vector realising each maximum measures it to zero in all 375 window and set pairs. Of six gates, one is true by construction, one never exercises the step it names, none bounds a ceiling from above -- a deliberately broken pooling step produced values of 1.32 while three still passed -- and the only check with unique catching power covered 1.1 per cent of the evaluations |
- What none of that establishes — each pass is rank one against five, nine or nineteen permutation worlds, which is not a p-value, and none is an independent estimate of its own size: sizing saw the numbers before the contracts were frozen, and the third row's shape was chosen after a different one failed. The seven rows before the last five are sizings, with no contract and no floor; in two of them the rival arm was designed after seeing the round it rivals, and the quarter the last five of those report on cannot be acted on at all, because which cells fall in it is fixed by the labels of the window being scored. The four rows before the last four withdraw readings of my own that audits blocked and that I recomputed before accepting; in the two before the last five the blocking faults were all in the design, before any number existed, and in the one before the last five a post-run audit then narrowed a pass rather than blocking it. The row four before the last is a verdict on that sizing, and every window it uses had already been looked at. The row three before the last is the first test of that increment on windows never looked at for it, and it fails at a power that was low and measured in advance, so it does not show the increment is absent. The row two before the last is a sizing with no floor whose declared observable was taken off it by its own post-run audit, so it reports a within-window activity term and not depth. The row before the last is a sizing too, with no floor and no contract, and its predictor's margin is measured against marks I built after seeing the first result, so only the bound in it is a proof; its windows share almost all of their training rows, so a bias in the feature set would show in all of them at once. The last row is a sizing as well, its headline is an exclusion rather than an effect, its floor covers the single fields and not the models, and the comparison it rests on was re-run after an audit found that the first run had scored a rule the contract does not contain. Event-by-event discrimination has not been demonstrated, and magnitudes are not compared across catalogues, so no global row is a statement about Japan
- Open data & automation — features published as a public Hugging Face dataset, weekly CI pipeline on GitHub Actions
- Co-seismic InSAR — 2026 Kumamoto M7.1 measured from open Sentinel-1 on ASF HyP3: line-of-sight displacement −21.7 to +15.0 cm and a coherence-change damage proxy (method, figures and caveats)
Japan Wildlife Sightings — Bear and wildlife sighting open data, normalized · map
Why it exists, what is collected, and what is withheld
- The data is public but incompatible — prefectures publish bear, boar and deer sightings as CKAN CSV, ArcGIS Survey123, Google My Maps KML, Excel or PDF. The Ministry of the Environment publishes monthly totals as PDF only, so no nationwide point dataset exists. The aggregators that do exist are closed.
- 27 sources, 79,394 records in one schema (75,743 with coordinates), rebuilt daily on GitHub Actions and checked by a validator that counts coordinates, dates and duplicate ids.
- Only what the terms allow is published — 40,241 records from sources that state CC BY or PDL 1.0 (Akita, Kyoto, Ishikawa, Kanazawa, Yamaguchi, Sapporo, Muroran, Ishikari, Kamisunagawa). Every other source ships as a fetcher, not as data, with the licence wording quoted in docs/licenses.md.
- Finding the data is most of the work — a prefecture page often links only a PDF while a public ArcGIS layer sits behind its map (Toyama 4,614 records, Fukushima 4,491). Most PDF-only prefectures publish monthly totals rather than per-incident rows; the two that don't are parsed back, one by layout and one by glyph coordinates.
- A map, not just a file — MapLibre GL JS over GSI tiles, GSI aerial photography and NASA GIBS VIIRS imagery from the previous day. Library and glyphs are vendored, so the page depends on no external CDN.
| Project | Description | Demo |
|---|---|---|
| NPB Season Prediction | Bayesian ensemble (Marcel 35% + Stan/Ridge 40% + ML 25%) + Monte Carlo team simulation + 24 foreign player individual projections | Live |
| NPB 2021 Backtest | Could Bayesian model predict Yakult & Orix last→champion? 25 foreign players with FanGraphs data | Analysis |
| MLB Win Probability Engine | 3-engine ensemble WP (Normal + Empirical + LightGBM) + Gemini AI commentary | Live |
| Baseball MLOps Pipeline | Statcast MLOps: 5-model ensemble — weekly auto-retrain paused (BigQuery retired 2026-04, data layer being rebuilt on Hugging Face) | Live |
| MLB Data Pipeline | Shared data platform — FanGraphs + Savant + Statcast published as a public Hugging Face dataset, weekly auto-refresh via GitHub Actions | HF Dataset |
Prediction accuracy & details
| System | Key Metric | Articles |
|---|---|---|
| NPB 2026 | 8-yr backtest wOBA MAE .0498, 97% prob. of beating Marcel. 10K Monte Carlo sims | JP / EN |
| NPB 2021 Backtest | MAE 10.7W — Yakult & Orix last→champion driven by JP player breakouts, not foreign players | Repo |
| MLB WP Engine | 3-engine ensemble, 367K+ play states (2015–2024), inverse-Brier weighted + Isotonic calibration | Live |
| Baseball MLOps | Batter wOBA MAE .0287 (Marcel: .0326) / Pitcher xFIP MAE 0.483 (Marcel: 0.558) | Live |
Baseball Skeleton Analysis — 3D skeleton visualization from Driveline OpenBiomechanics C3D data
| Pitching Skeleton (3D C3D) | Hitting Skeleton (3D C3D) |
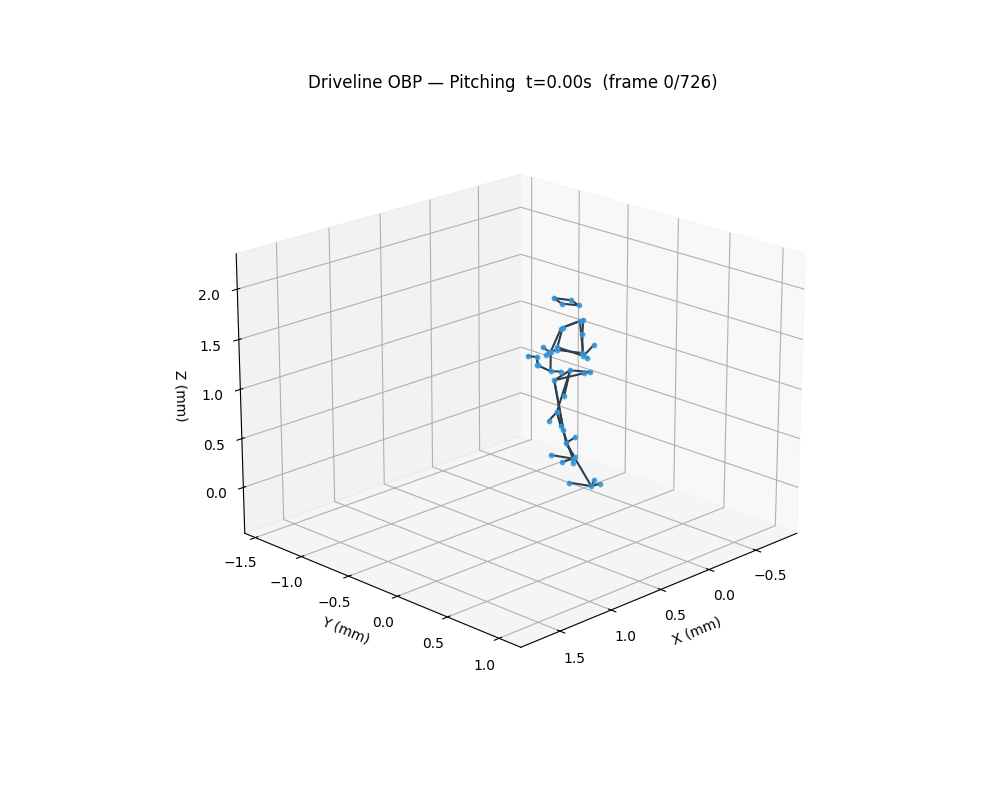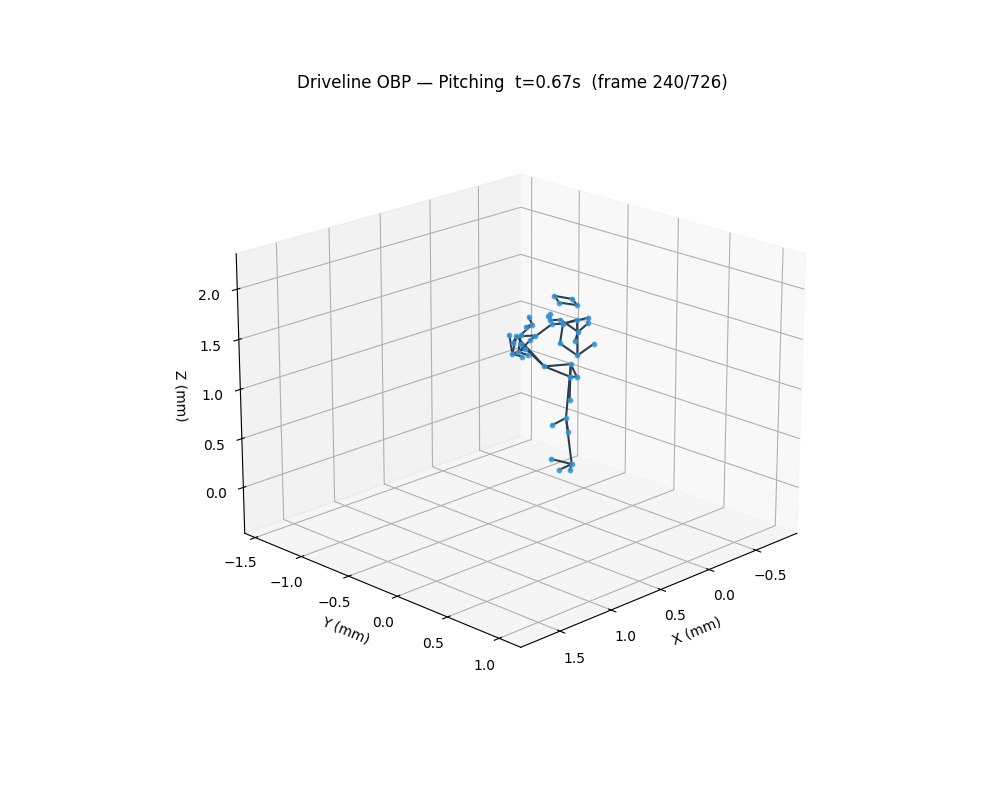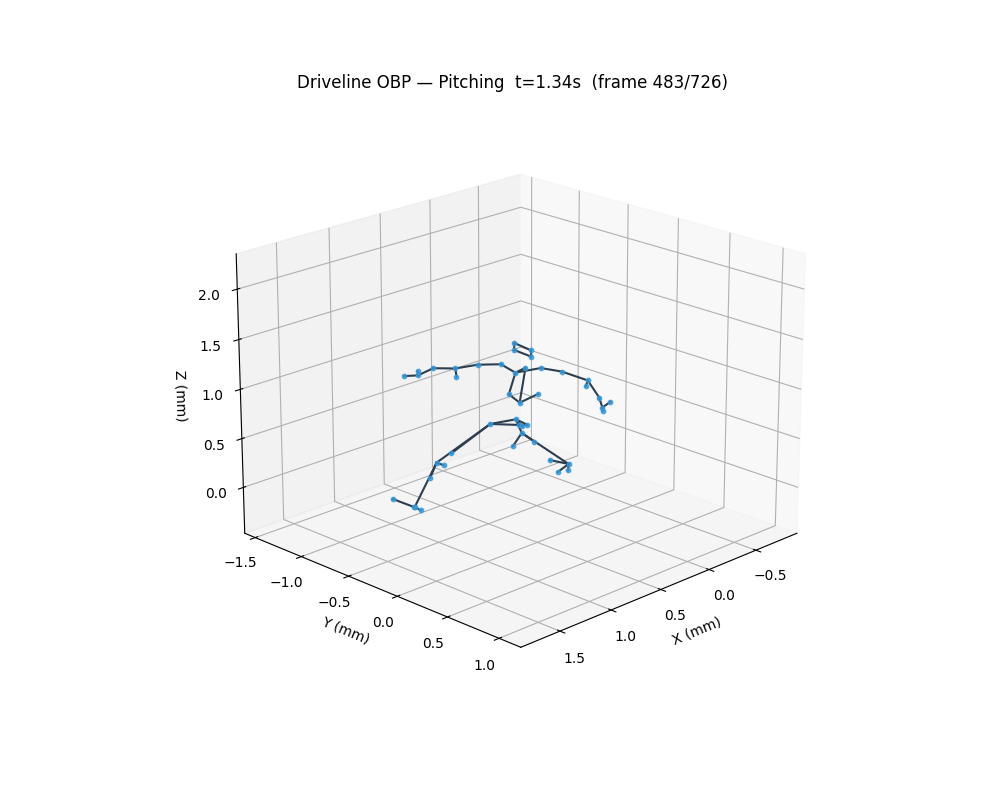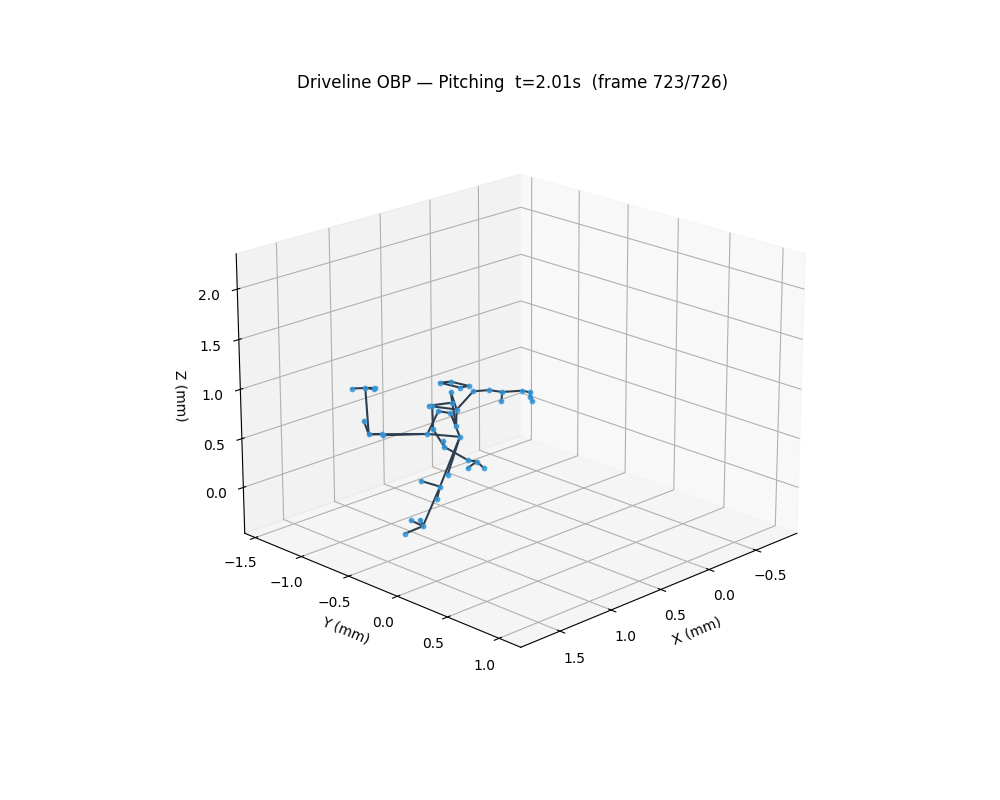 |
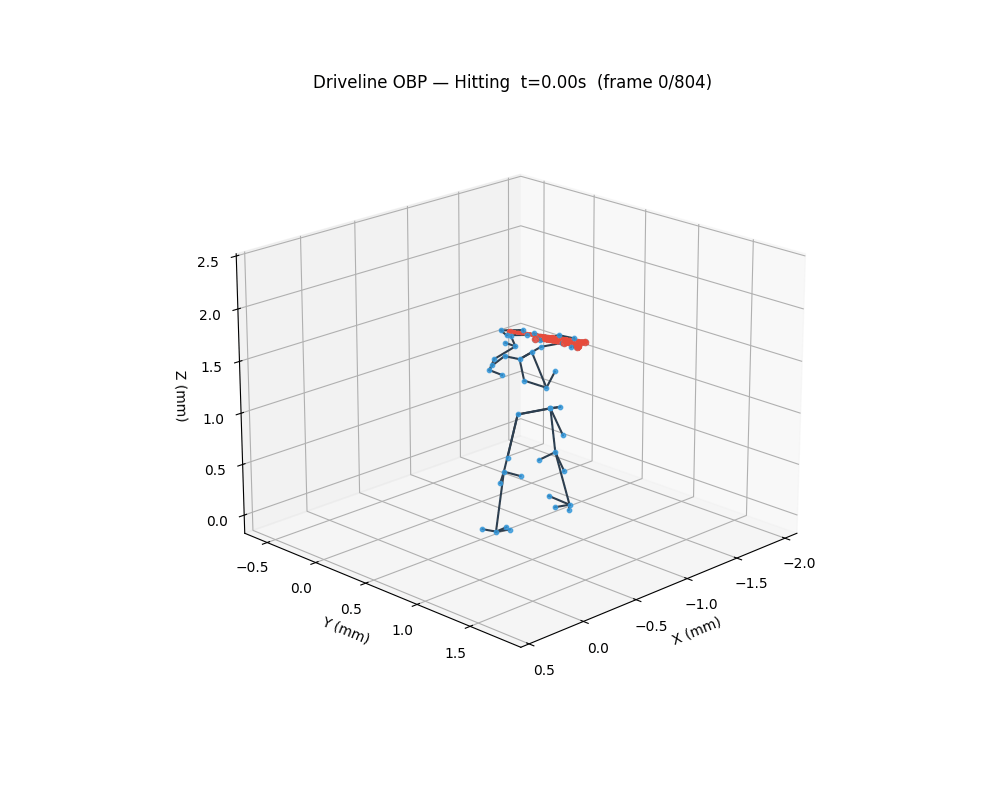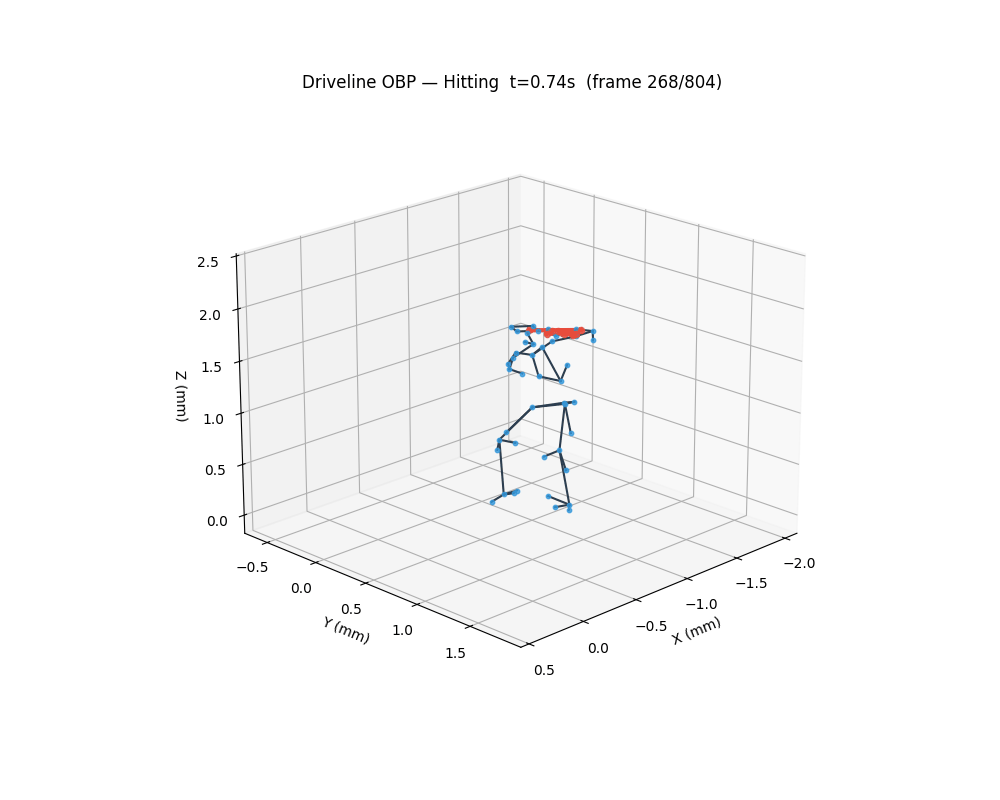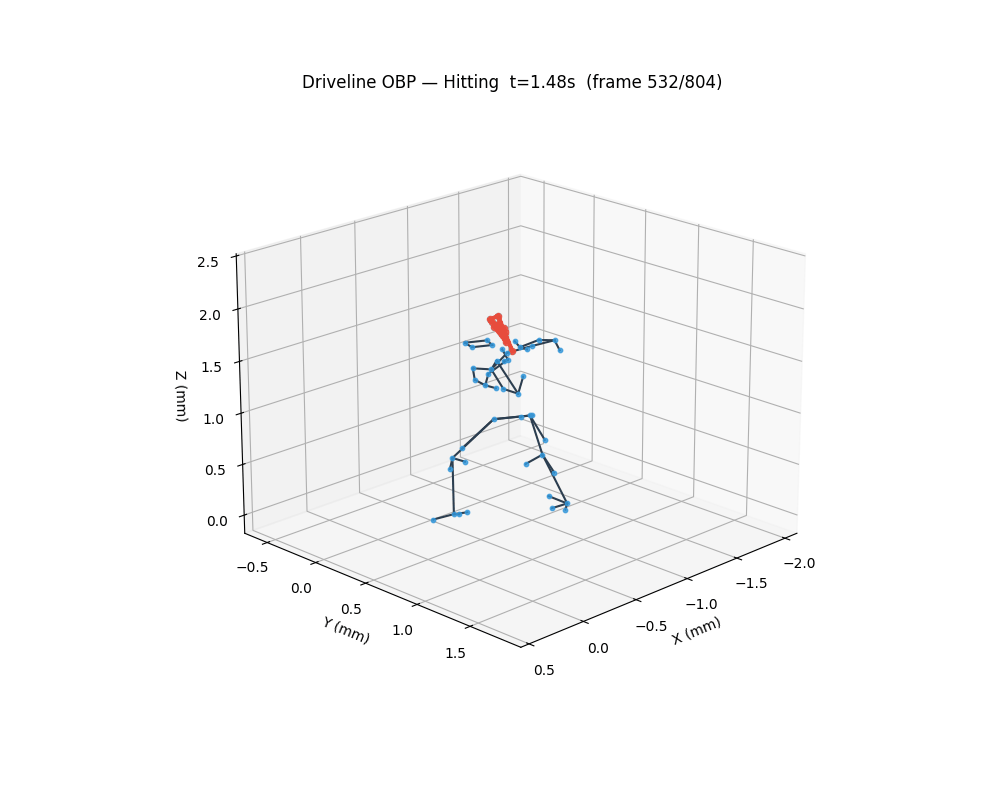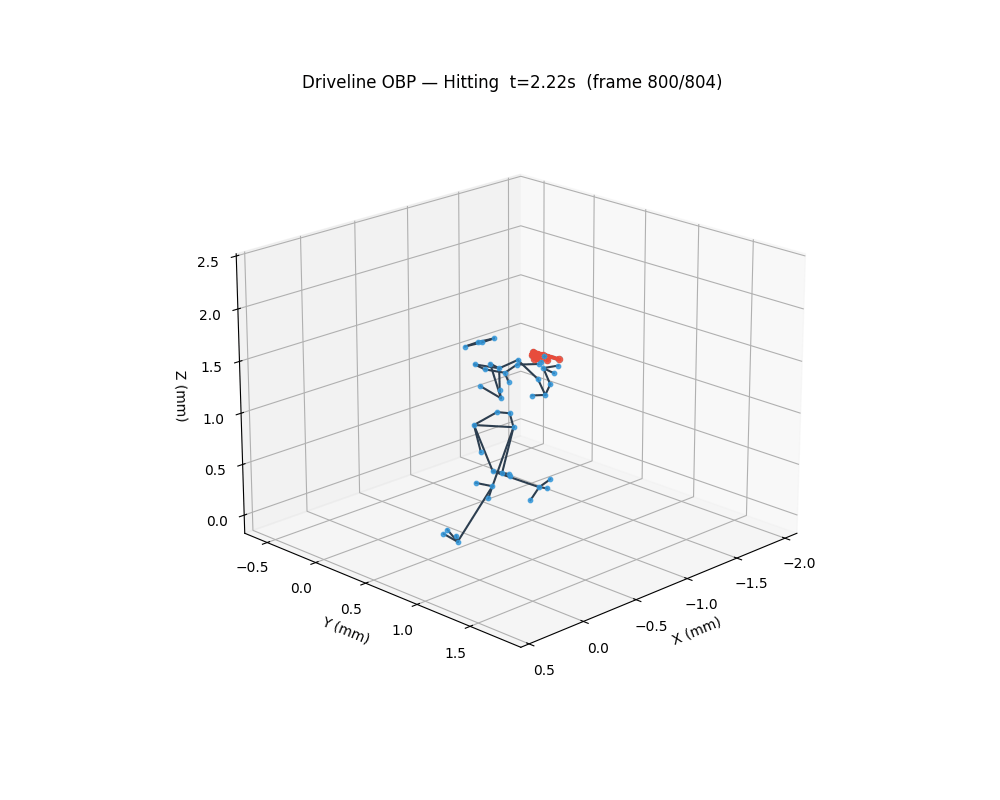 |
Trunk rotation range vs pitch speed: r=0.425 (strongest). Contributed bug fix PR #384 to ezc3d. Article (JP) / Article (EN)
6 analyses covering Japanese MLB pitchers and Ohtani batting data.All analyses (6)
| Analysis | Key Finding | Article |
|---|---|---|
| Kikuchi Slider Revolution (2019-2025) | SL 17%→37% after Astros trade | Zenn / DEV.to / Kaggle |
| Senga Ghost Fork (2023-2025) | FO whiff rate 58%→39%, decline pre-injury | Zenn / DEV.to / Kaggle |
| Imanaga 2nd Year (2024-2025) | 3-pitch concentration (97%), 1st TTO xwOBA .505 | Zenn / DEV.to / Kaggle |
| Darvish Evolution (2021-2025) | SL/ST halved, CU became putaway pitch | Zenn / DEV.to / Kaggle |
| Ohtani Spray Chart | spraychart() one-liner vs matplotlib manual | Zenn |
| Ohtani Heatmap | Stadium drawing + hit density heatmap | Zenn |
Two deterministic readers of documents nobody else could read — one handwritten, one printed. Neither sends a page to a cloud OCR or to a generative model, and the same page always reads back the same.
Handwritten Scorebook OCR 🔒 (private R&D, active)
Reads handwritten Japanese paper scorebooks (紙スコアブック) from photos into structured at-bat data — no paid API, no cloud OCR · deterministic OpenCV on a Raspberry Pi 5 · a base-running constraint solver decides what the marks mean · graded on 33 hand-transcribed sheets
Where it stands
| Configuration | Score |
|---|---|
| Grid facts handed over (shipped default) | 366 / 396 = 92% |
| No grid fact handed over at all | 363 / 396 = 92% |
| ...and every recognition in-house as well | 330 / 396 = 83% with the ledger kept, 283 / 396 = 71% with no ledger at all |
| A price order picked after seeing the result, re-judged on two sheets it never saw | refuted -- 30 vs 34 on those forty corners, last of the four places the term can take, and 28 vs 29 with every recogniser on; its +28 across the corpus sits on the sheets that chose it. Shipping default unchanged |
| Hardest mark class: template matching alone → fused with the solver | 76% → 93% |
| Consecutive held-out sheets — each new game is graded before it joins the pool | 31 |
| Real output | my team's 2026 season batting stats are compiled from this ground truth |
What the last rounds changed
| Change | Result |
|---|---|
| Which column is which inning: cut from the ledger, read off the paper | A gate demanding each inning read exactly {I, II, III} left the truth reachable on 3 sheets of 31; pricing it instead reaches all 31 |
| The last hard gate — an inning holds at most three batter outs — allowed to be outbid | Worth 36 corners where the out/reach call is made in-house, under a price order arrived at after the fact. With every recognition in-house as well, the gap to reading the ruling lines back falls from 43 corners to 4 |
| Adversarial review of the diagnostic behind that claim | It had been run without the flag it was describing, so the number meant something else. Re-measuring properly is what produced the 36 above |
| Nine ways to stop spurious marks pinning the wrong batter | All null, against a measured ceiling of +14 corners |
Private repo (the method is the product) — public technical write-up: baseball-scorebook-ocr-docs (JP)
Business-Form PDF Extraction 🔒 (private R&D, active)
Turns supplier PDFs into the spreadsheet a back-office system can ingest — with no generative model anywhere in the read path, because one invented unit price is a wrong receivable. Same PDF in, same bytes out, every time · standard library only (nothing is installable on the target machines) · it reconciles against the total the form itself prints.
Why not a generative OCR
Measured on a dense 56 × 5 alphanumeric part-number grid:
| Check | Result |
|---|---|
| The same number read across two passes | prefixes swap between runs; Q↔0, case flips, digit counts drift |
| Two-pass agreement on the worst page | about half — majority voting does not converge |
| Where the two methods disagreed | every mismatch was the generative side misreading |
| Duplicates it reported | 14 — all distinct parts it had misread. True duplicates: 0 |
A generative reader is bad at exactly this shape of input: dense, uniform, alphanumeric, and unforgiving. The fix is not a better prompt — it is not giving it the job.
How it reads instead
| Layer | What it does |
|---|---|
| Opening the file | raw PDF bytes, standard library only — both legacy xref tables and xref streams |
| Ambiguous digit boundaries | every candidate split is tried; only the one where qty × unit price = amount survives |
| Rows and columns | taken from the printed ruling lines and the header, never from coordinate thresholds — so uneven row heights, values wrapped across two lines, and rows continuing onto the next page all behave the same |
| Pages that are neither text nor raster | outlined glyphs are rendered, clustered by shape, labelled once by eye, then the strings are rebuilt — zero OCR jitter, fully reproducible |
| Document types | three of them, told apart from the structure of the file itself; the operator's three steps never change |
| Output | as-is. If the form prints the same part twice, it comes out twice; if there is no list to read, it says so and stops instead of writing an empty sheet |
What it was graded against
| Check | Result |
|---|---|
| Full-row, full-column reconciliation against independently keyed human data, 3 months | 269 / 229 / 855 rows — exact match |
| The one mismatch | the human data was wrong — a unit price keyed as 0 where that row's own quantity and amount imply 3.20, and the form prints 3.20. Confirmed with the owning department; the tool keeps the form as truth |
| Vector-grid corpus | 2,526 parts, 0 duplicates, order-sensitive |
| Regression method | the previously shipped engine is pulled back out of the distributed notebook and re-run on the same PDFs — byte-level diff, not eyeballing |
| Bugs with no reproducing case in the corpus | synthesised the byte sequence that triggers them, showed old-breaks / new-holds, then shipped |
| Corrections logged against my own earlier conclusions | 3 — including "this document has no part list", which was my own parser truncating the page early |
Private repo (the method is the product). What is kept there is the method and the judgement calls — no customer documents, no counterparty names.
(133 PRs / 86 Merged) across 49 repositories. See [oss-contributions](https://github.com/yasumorishima/oss-contributions) for full details.PR highlights (click to expand)
| Repository | PR | Description |
|---|---|---|
| dfinity/icp-js-core | #1270 | Improve Candid decode error messages |
| line/line-bot-mcp-server | #369 | Add get_follower_ids tool |
| pyomeca/ezc3d | #384 | Fix __eq__ early return bug |
| codeforjapan/mapprint | #556 | Share buttons on the disaster print map |
| codeforjapan/mapprint | #564 | Deterministic list order on the printable map |
| codeforjapan/mapprint | #563 | 2026 Kumamoto earthquake paper map |
| codeforjapan/BirdXplorer | #281 | Statement timeouts for the Community Notes API |
| hotosm/openaerialmap | #289 | Stop the STAC ingester dropping the wrong record when an entry fails |
| apache/fineract-backoffice-ui | #321 | Translate the accounting screen titles and tooltips |
| daisy/MathCAT | #665 | Fix chemistry assertions that could never fail |
| daisy/MathCAT | #720-778 | Japanese speech rules, 23 merged PRs: fractions in Japanese word order, exponents, negative numbers, roots, geometry terms, brackets, large operators, intervals, mathematical vocabulary, elementary functions, accents, symbol readings, function application, nPk permutations, menclose marks, the navigation command prefixes, the rule vocabulary, the shared-rule vocabulary, the set-theory readings, the navigation phrases that were still spoken in English and the strings promoted to verified |
| daisy/MathCAT | #746 | Fix the Japanese navigation announcements a blind reader hears on every move, including four that stated the opposite of the truth at the edge of a table |
| PHPOffice/PHPPresentation | #897 | Fix PHP 8.4/8.5 static analysis by fixing 144 findings instead of ignoring them |
| project-inclusive/OpenFisca-Japan | #479 | Add the vocational training benefit for single-parent families to Japan's welfare rules engine |
| project-inclusive/OpenFisca-Japan | #480 | Add the housing security benefit to Japan's welfare rules engine |
| project-inclusive/OpenFisca-Japan | #481 | Add the welfare loan fund for single-parent families and widows to Japan's welfare rules engine |
| project-inclusive/OpenFisca-Japan | #482 | Add the school-cost assistance eligibility check to Japan's welfare rules engine |
| project-inclusive/OpenFisca-Japan | #483 | Add the higher-education tuition and entrance-fee reduction to Japan's welfare rules engine |
| project-inclusive/OpenFisca-Japan | #484 | Add the jobseeker support benefit paid during free vocational training to Japan's welfare rules engine |
| optuna/optuna | — | Hyperparameter optimization framework |
| pandas-dev/pandas | — | Data analysis library |
| jldbc/pybaseball | #498-504 | Bug fixes & documentation |
team-mirai — Civic Tech OSS (26 PRs (14 Merged / 4 Open / 8 Closed))
Civic tech projects for political transparency & citizen participation in Japan. Next.js / TypeScript / Supabase / Vitest.
| Repository | Highlights |
|---|---|
| action-board | 48 unit tests, RPC tests, breadcrumb nav, cache fix + 5 more |
| mirai-gikai | Supabase CLI v2.106 seed permission fix, Safari/iOS ruby spacing fix |
| fact-checker | X API investigation + 5 PRs |
Notebooks Expert | 🥉 15 Bronze Notebook Medals
Active:
- SIGNATE NEDO Challenge — Baggage-Loading Optimization — 3D bin packing for airline ULD containers, hybrid offline+online packing agent (¥15M prize pool, Jul–Oct 2026) — public score 51.33 as of 2026-09-21 (456 teams, top-10 cut 69.42), scored on fill rate, centre of gravity, stability under shaking and placement of priority/soft cargo. A candidate position was ranked by the surface it rests on and never by how tall the bag would then stand, so a tall thin orientation won a low gap over a flat one — 35 to 50 per cent of the moves in the episodes that end early, and more wasted height in total than the container is tall. Ranking by the resulting top instead is worth +1.02 on one task type and +0.32 on another. The five scored components are additive across task types to three decimals, so any task-conditional mix of measured versions can be priced without spending a submission
- 5th Air Combat AI Challenge (SIGNATE, run by Japan's Acquisition, Technology & Logistics Agency) — behaviour-decision agents for a 4-fighter plus 1 escorted-aircraft engagement in the organiser's simulator · Glicko-2 rating over agent-vs-agent matches · entries stay private until the contest closes (¥1.92M prize pool, to 2026-12-04)
- Kaggriculture — two-player farm-economy simulation, scored by ladder rating rather than by money ($50K prize pool, to 2026-09-30) — the submitted agent wins 0.91 of 96 paired games against the one it replaced, on a lever the per-product ledger found rather than a tuned one: our first fleece reached the market on day 20 against a strong opponent's day 6. The ladder does not resolve that: a submission's rating is a forty-game walk that freezes when the next one replaces it, and three of ours sit at win rates 0.463, 0.434 and 0.432. Agent and its measurement harness in
kaggle-competitions/kaggriculture
Finished 2026: ROGII Wellbore Geology ($50K wellbore TVT regression, closed 2026-08-05 — public LB 7.311, final public rank 2545/6125) · Playground Series S6E6 - Stellar Classification (macro-F1, private LB 0.95939) · NIR Moisture Prediction (SIGNATE, wood spectroscopy) · Stanford RNA 3D Folding 2 · BirdCLEF+ 2026
Bronze Medal Notebooks (15)
| Notebook | Topic |
|---|---|
| savant-extras Defense & Pitching Quality | Defense metrics & pitching quality (savant-extras) |
| MLB Statcast Spray Charts for WBC 2026 | WBC 2026 spray + pitch zone charts (baseball-field-viz) |
| March Machine Learning Mania 2026 | NCAA tournament prediction (LightGBM) |
| NFL Geometric Rules Baseline | Physics-based rules, No ML, RMSE 2.921 |
| CAFA 6 Baseline | Protein function prediction (PyTorch MLP) |
| Dataset | Description |
|---|---|
| 🥈 MLB Bat Tracking Leaderboard (2024-2025) | 452 batters, 19 swing metrics |
| 🥈 WBC 2026 Scouting | 306 players, 20 countries |
Other datasets (6)
| Dataset | Description |
|---|---|
| Baseball Savant Leaderboards (2024-2025) | 15 leaderboards, 2 seasons combined |
| Japanese MLB Players Statcast (2015-2025) | 34 Japanese MLB players, 174k pitches+hits |
| MLB Pitcher Arsenal Evolution (2020-2025) | 4,253 pitcher-seasons, 111 metrics |
| MLB Statcast + Bat Tracking (2024-2025) | Combined Statcast + bat tracking data |
| XC BirdCLEF 2026 Target Recordings (URLs) | Xeno-canto source URLs for the 2026 target species |
| BEATs iter3+ AS2M Pretrained | Audio-tagging checkpoint mirrored for offline notebooks |
DrivenData Competitions — Automated pipeline: GitHub Actions + GPU training + GPU→CPU fallback. Most recently competed in On Top of Pasketti (Children's ASR, $120K prize, Wav2Vec2 CTC; submission deadline 2026-04-06).
| App | Description | Link |
|---|---|---|
| MLB Bat Tracking Dashboard | Leaderboard, Player Comparison, Team Lineup Builder. Powered by savant-extras | Live |
| WBC 2026 Scouting Dashboard | 30 Statcast apps across 19 countries. Zone heatmaps, spray charts, pitch movement | Live |
| Daily Diary | Flutter mobile app, 10 languages, offline-first, biometric app lock, daily reminder, Android Auto Backup, AdMob · screen-reader support (every tappable control labelled for TalkBack, mood selection state, live-region save celebration; CI fails the build if any control ships unnamed, audits the real accessibility tree on an emulator, and measures the spoken audio of every label) · links to Sansuu/Shogi/Sora (ja only) | Google Play |
| Fire Tablet Google Play Helper | Detects Fire OS from the browser UA, then lists the four required APKs in install order with step gating and saved progress | Live |
WBC 2026 Scouting Dashboard details (30 apps)
30 Statcast scouting apps across 19 countries (batters + pitchers). Zone heatmaps, spray charts, pitch movement, LHP/RHP splits. Auto-fetched via GitHub Actions. → USA Batters / Japan Pitchers / All 30 apps
icrc167-android — Internet Identity login for native Android (Active)
The relying-party side of ICRC-167, so an Android app can sign a user in with Internet Identity and then call canisters directly — no bridge server and no backend of its own. An iOS implementation exists; the Android counterpart did not.
Seven things that were measured rather than assumed
| Question | What the measurement said |
|---|---|
| Does the URL fragment survive an App Link hand-off? | It does — 379 bytes, matching SHA-256, over both delivery paths. The transport returns the delegation there and nowhere else, while intent-filter matching ignores the fragment entirely, so it was worth checking rather than assuming. The same run caught Uri.getFragment() percent-decoding the payload and inventing a parameter that was never sent |
| Does the device test prove anything? | Not at first. The principal is derived from the root key in the response, so a passing positive case would have passed just as well with signature checking removed. The negative cases — an answer carrying somebody else's state, a signature that does not verify — are the test; the positive one only shows the parts still fit together |
| Is the hash right? | The same function produced the bytes that get signed and the bytes that get verified, so it agreed with itself and with nothing else. It is now pinned to the worked request-id example published in the interface specification |
| Do the negative tests reach the check they are named for? | The pairing equation did not. Replacing it with return true left every test green, because each negative case altered a byte of a compressed point and so died at the decoder or the subgroup check first. It is pinned now by cases where only the equation can decide — with the mutation pushed to CI both before and after, rather than reasoned about |
| Can the round trip be tested before Internet Identity is in the picture? | Yes — any Ed25519 key may delegate, so a chain signed here comes back from mainnet as the principal that delegated, and the same chain signed by the wrong key is refused |
| Do the published test vectors settle the rules? | Not all of them. A delegation must state its subnet's type; no canister signature in the public record carries it and a certificate fetched from id.ai does — the vectors are simply older than the rule |
| Does verifying the certificate bind the answer to the canister? | Not on its own. The canister-range check runs only when the certificate is delegated; an undelegated one verifies to the root key without ever looking at the canister, and the root state tree holds the node keys of every subnet. One genuine certificate would otherwise let any node answer for anything, so the binding is made explicitly |
A demo app is out, built to sign in with Internet Identity, ask a canister who it sees, check the node signature and print PASS or FAIL; on 2026-09-14 it signed in on a real phone with a real passkey and printed three PASSes, after the lifetime check stopped refusing Internet Identity's 30-day outer hop. Until 2026-09-11 the default verifier refused every real chain. On 2026-09-15, in Chrome, Edge and Brave (all Chromium 153), the passkey prompt did not come for Internet Identity's credential list while Google Play services logged Transport smart-card not supported; the same list with internal and hybrid transports went through in one run. Reported as dfinity/internet-identity#4334, and closed: from 153.0.8010.47 Chromium no longer sends the smart-card transport, a browser change rather than a Play services one, so it reaches each Chromium browser on its own release.
Kotlin / Android (Custom Tabs, App Links, Keystore) / BLS12-381 · Ed25519 · ECDSA P-256 · SHA-256 / CBOR / GitHub Actions (JVM tests + emulator)
6 packages (click to expand)
| Package | Description |
|---|---|
| savant-extras | 17 Baseball Savant leaderboards + date range support. Complements pybaseball |
| baseball-field-viz | Statcast coordinate transform + field drawing + spray charts + pitch zone charts |
| kaggle-notebook-deploy | Deploy Kaggle Notebooks via git push + GitHub Actions |
| kaggle-wandb-sync | Sync W&B offline runs from Kaggle to W&B cloud |
| signate-deploy | SIGNATE competition workflow via GitHub Actions |
| signate-wandb-sync | Record SIGNATE scores to W&B runs |
| Project | Description |
|---|---|
| Sansuu, Shogi & Sora | Four modes on the Internet Computer: arithmetic (36 calculation topics + 31 word-problem topics, read aloud on request) · shogi · sora, a planetarium drawing the real sky for any place and time · play, six toddler games — moles, balloons, spoken picture words (with a note when the device has no voice to speak them), fish, finger drawing and sound bars — none of which asks the child to read a letter. Usable without sight — the sky is spoken (direction in degrees, altitude, nearest object) and every game answers the screen reader and the keyboard. The background changes with the season — colour, falling petals/bubbles/leaves/snow and a drawn scene, the sun becoming a moon at night. Every picture is drawn by hand: of the 23 emoji the site used to show, 11 rendered as empty boxes on a device without an emoji font, so all of them are SVG now. English/Japanese, offline, records on-device — Live |
| OpenClaw Twitter Bot | Raspberry Pi 5 + OpenClaw + Gemini API auto-tweet bot (stopped) — Article (JP) |
| alexa-rpi5 🔒 | Raspberry Pi 5 to Fire TV Cube control hub for a house with no Echo speaker: cube wrapper, watchers and integrations (details in the repo README) |
Past Projects
| Project | Description |
|---|---|
| GAS Calendar Tool | Batch calendar event registration with senior-friendly mobile UI |
| Dune Analytics | On-chain data analysis — JPYC Stablecoin Dashboard |
| selenium-to-playwright 🔒 | Playwright browser automation: 20+ scripts + night batch runner with auto GitHub Issues |
| Archived Projects | Selenium automation, business workflow tools, etc. |
| Category | Technologies |
|---|---|
| Data Analysis & ML | Python, pandas, scikit-learn, LightGBM, XGBoost, CatBoost, PyTorch, matplotlib, seaborn, DuckDB, W&B |
| Data Platform | Hugging Face Datasets (MLB / NPB / geohazard — public, auto-refreshed via GitHub Actions), SQLite, |
| Data Sources | Baseball Savant (Statcast), pybaseball, USGS, NASA Earthdata, AIS |
| Web & Dashboards | Streamlit, Next.js, TypeScript, Supabase, Vercel, shadcn/ui |
| Mobile App | Flutter, Dart, Hive, Google AdMob |
| Automation & DevOps | GitHub Actions, Google Apps Script, VBA, Power Query |
| Tools | Claude Code, Kaggle, Google Colab, Excel, Looker Studio |
| Manufacturing | Statistical Quality Control, Process Engineering |
- 2024 - Present: Quality Management @ a semiconductor distributor
- 2008 - 2024: Semiconductor Manufacturing Process Engineer
- 2008 - 2014: Toppan Printing
- 2014 - 2017: Toshiba → Toshiba Memory (now Kioxia)
Stencil mask and manufacturing method thereof
- Patent No: 6307851
- Role: Inventor
- Link: Google Patents (JP6307851B2)
- Site: https://yasumorishima.github.io — tools and blog hosted on this domain
- Blog: DEV.to (EN) / Zenn (JP) / Quarto Blog (EN)
- Kaggle: https://www.kaggle.com/yasunorim
- Wantedly: https://www.wantedly.com/id/yasunori_morishima_b
- LinkedIn: https://www.linkedin.com/in/morishima-yasunori-b70229241